
Binary File: What It Is & How It Differs From Text
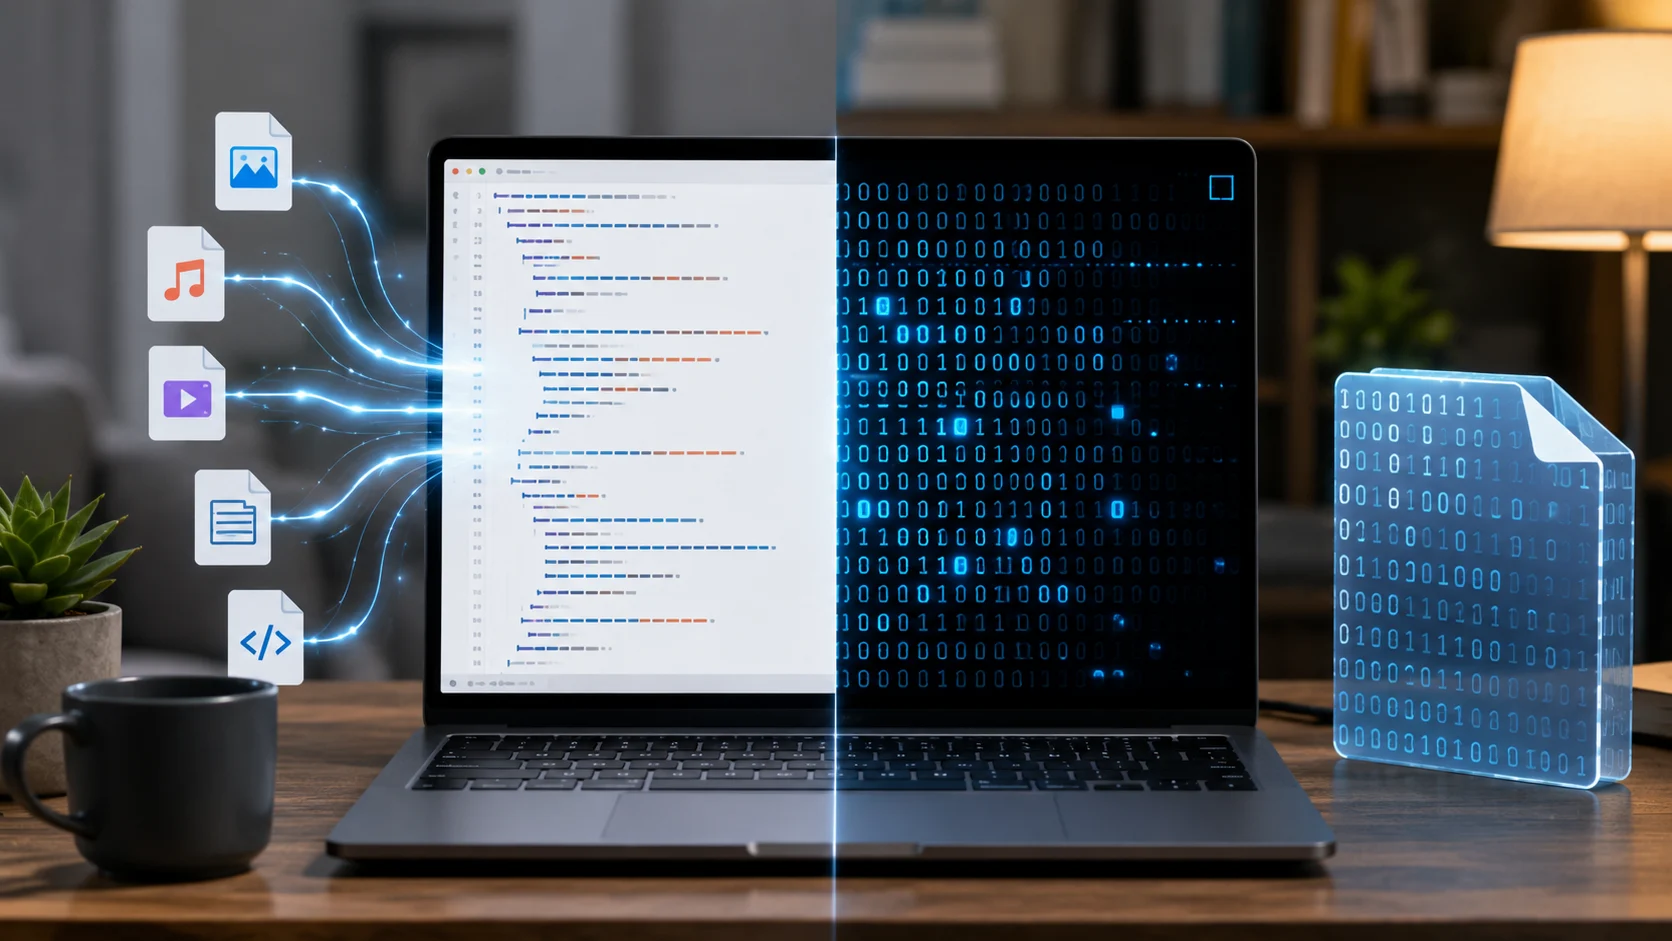
A binary file is a computer file that stores information in a format designed primarily for software rather than direct human reading. Like every digital file, it ultimately consists of bits represented as zeros and ones, but its bytes may represent images, instructions, audio samples, compressed data, numbers, or structured records instead of ordinary text characters. Common binary file examples include JPEG images, MP3 audio, PDF documents, executable programs, compressed archives, and many database files. These files normally require an application that understands their format before their contents become meaningful. Opening a binary file in a basic text editor often produces unreadable symbols because the program interprets arbitrary bytes as characters. Understanding binary files helps explain how computers store complex information efficiently.
Binary files are often compared with text files because the distinction affects how programs store, transfer, inspect, and process information. A text file represents its content using character encodings such as UTF-8, making much of the data readable in an ordinary editor. A binary file can represent values directly according to rules defined by its file format, often making storage more compact or processing more efficient. Developers work with binary data when handling multimedia, executables, network protocols, databases, serialized objects, and compressed information. Users encounter binary formats every day even when they never see the underlying bytes. This guide explains what a binary file is, how binary data works, how it differs from text, common examples, file structures, and practical ways to inspect binary files.
What Is a Binary File?
A binary file is a file whose contents are interpreted according to a structured binary format rather than primarily as a sequence of human-readable characters. The bytes inside the file may represent integers, floating-point values, compressed blocks, pixels, machine instructions, timestamps, or other forms of information. A program needs to know the format rules before it can correctly interpret those bytes. For example, several consecutive bytes in an image file might describe dimensions or color information rather than letters. The same byte value can therefore mean completely different things in different file formats. Context provided by the file specification determines what each section represents.
It is important to understand that all files are binary at the physical storage level because computers store information using bits. Text files are not somehow made from a different type of computer data. The distinction comes from how the byte sequence is intended to be interpreted. In a text file, byte patterns usually correspond to characters through an encoding such as UTF-8 or another character set. In a binary file, those bytes can encode many types of structured information without needing to correspond to printable characters. Therefore, saying “binary file” normally means the file is not intended to be interpreted primarily as plain textual characters.
Consider a simple image as an example of binary data. The file may contain a header identifying the image format, information about width and height, color characteristics, compressed pixel data, and other metadata. Those values are stored as bytes according to the image specification. A photo viewer reads the structure, decompresses information when necessary, and displays the resulting pixels on the screen. If the same file is opened in a plain text editor, the editor does not understand those structural rules. It simply attempts to display arbitrary byte values as characters, producing text that may appear corrupted or meaningless.
Binary files often use specific filename extensions that indicate which application or format is associated with the content. Examples include .jpg, .png, .mp3, .exe, .zip, and many other extensions. However, the extension itself does not define the actual contents of the file. Renaming an image from .jpg to .txt does not transform its binary image data into readable text. The underlying bytes remain unchanged until software actually converts the format. This is why operating systems and applications may examine file signatures or internal metadata in addition to relying on the filename extension.
Binary file formats can be publicly documented, standardized, proprietary, or specific to one application. A public format allows different software developers to create compatible readers and writers based on the same specification. Proprietary formats may require specialized software or reverse engineering when documentation is unavailable. Some formats remain stable for many years, while others evolve through different versions that introduce new fields or capabilities. Programs reading binary files therefore need to recognize which version or variant they are processing. Good format design often includes identifiers and version information that make compatibility easier to manage.
How Binary Files Store and Organize Data
Binary files organize data as sequences of bytes, with each byte normally containing eight bits. The meaning assigned to those bytes depends entirely on the file format and the software interpreting it. One byte might store a small number, several bytes might form a larger integer, and another region might contain compressed multimedia data. The file can also include flags where individual bits indicate whether particular options are enabled. Because values can be stored directly rather than written as textual digits, binary representations can be compact. This direct representation is one reason binary formats are common in performance-sensitive and storage-intensive applications.
Many binary formats begin with a header containing information that helps software understand the rest of the file. A header may identify the file type, format version, dimensions, encoding method, number of records, compression scheme, or location of important data sections. Some formats use a recognizable sequence of bytes called a file signature or magic number. Applications can examine this signature to determine whether the file matches an expected format. After the header, the file may contain one or more structured data sections. The exact arrangement varies dramatically among image formats, executables, archives, databases, and multimedia files.
Numeric values can be stored in binary files using several representations. Integers may occupy one, two, four, eight, or more bytes depending on the range required by the format. Floating-point numbers can use standardized representations designed for fractional values and scientific calculations. Software must also know the byte order, called endianness, when interpreting multibyte numbers. Little-endian systems store the least significant byte first, while big-endian formats place the most significant byte first. If a program interprets the wrong byte order, the resulting numerical value can be completely different from what the file intended.
Binary files can also contain offsets or indexes that point to other locations within the same file. Instead of reading every byte sequentially, software may jump directly to a particular data structure based on an address stored in the header. This technique can make large files faster to navigate and update. Database formats, multimedia containers, and executable files frequently contain several organized sections with references connecting them. Tables may indicate where code, metadata, images, indexes, or compressed blocks begin. Structured organization allows one binary file to hold surprisingly complex information while remaining efficiently accessible to software.
Compression adds another layer of complexity because the bytes stored on disk may not resemble the original information directly. Formats such as ZIP, JPEG, MP3, and many video codecs transform information into more compact representations using compression algorithms. Software must decode or decompress the stored binary data before users can work with the original content. Some compression is lossless, meaning the original data can be reconstructed exactly. Other methods are lossy and intentionally discard selected information to reduce size substantially. Binary files are particularly well suited to these techniques because their internal structure can represent compressed bit patterns efficiently.
Binary File vs Text File: What Is the Difference?
The main difference between a binary file and a text file is how the stored bytes are interpreted. A text file represents information primarily as characters, usually through an encoding such as UTF-8. This makes files such as source code, configuration files, Markdown documents, and many logs readable in basic text editors. A binary file can use arbitrary byte values to represent structured or encoded information that has no direct character equivalent. It therefore usually requires specialized software to display its meaningful contents. Both types consist of bytes, but they follow different conventions about what those bytes mean.
Human readability is one of the clearest practical differences. If a developer opens a .txt, .csv, or source code file in a text editor, most of the content can usually be understood immediately. Opening a JPEG image or executable file in that same editor often shows unusual symbols, empty boxes, or fragments of recognizable text surrounded by unreadable data. The binary file is not necessarily damaged. The text editor is simply using the wrong interpretation for the bytes. A dedicated image viewer or executable loader understands the format and can translate those bytes into useful information.
Storage efficiency can also differ between binary and text representations. Suppose a program needs to store the number one million. Written as text, 1000000 requires seven character positions, usually at least seven bytes in common encodings. The same value can fit into four bytes as a conventional 32-bit binary integer. Differences can become substantial when millions of numerical values are stored. However, compactness depends on the format, because text can also be compressed and binary formats may contain substantial metadata. Binary does not automatically mean smaller, but it often allows more efficient representation of structured numerical information.
Text formats generally have advantages for inspection, editing, debugging, and interoperability. Humans can open a JSON, XML, CSV, or plain configuration file and modify values without writing a custom decoding program. Text-based formats are therefore popular for configuration, source code, web APIs, and data exchange where transparency matters. Binary formats are often preferable when compact storage, high processing speed, multimedia representation, or precise data types are more important. Neither approach is universally superior. Developers choose based on performance, compatibility, maintainability, file size, and how the data will be used.
Another difference appears when files move between systems. Text files may require attention to character encoding, newline conventions, or Unicode handling, while binary files generally require byte-for-byte preservation. Historically, some file transfer systems distinguished between text and binary transfer modes because text mode could modify line endings during transmission. Such modification would corrupt a binary file because every byte may have a precise structural meaning. Modern transfer tools usually preserve files safely without users needing to think about this distinction. Even so, the principle remains important: arbitrary changes to bytes inside a binary file can make the format unreadable.
Common Examples of Binary Files
Image files are among the most familiar binary file examples. JPEG, PNG, GIF, TIFF, and many other image formats contain structured information describing pixels, color models, dimensions, compression, transparency, and metadata. The underlying bytes are interpreted by graphics software according to the selected image specification. Compressed formats such as JPEG do not simply store every pixel independently because that would produce much larger files. Instead, mathematical transformations and compression techniques represent the image more efficiently. Photo viewers and browsers decode those binary structures before displaying an image. Users therefore interact with the visual result rather than the raw file contents.
Audio and video formats are also binary because multimedia requires large amounts of structured numerical data. MP3, AAC, WAV, MP4, and similar formats can contain encoded audio samples, video frames, timestamps, compression parameters, subtitles, and metadata. Video container formats may combine several independent streams inside one file. A media player reads the container, identifies the codecs required, and decodes each stream during playback. Modern compression makes high-resolution streaming possible by reducing enormous raw media datasets to manageable file sizes and network bitrates. These files demonstrate how sophisticated binary representations can support information that plain text could not represent efficiently.
Executable programs are another important binary category. Files such as Windows executables and many compiled applications contain machine instructions and structural information needed by the operating system. The file may include program code, libraries, resources, symbols, initialization information, and sections describing how content should be placed into memory. When a user launches the program, the operating system loader interprets the executable format and prepares the process for execution. The processor can then execute the machine instructions produced by a compiler. Changing random bytes in an executable can alter instructions or metadata and cause the application to crash or behave unpredictably.
Compressed archives such as ZIP and many similar formats are binary files that package one or more files together. The archive contains metadata describing filenames, directories, sizes, compression methods, and integrity information alongside compressed file content. Archive software reads this structure to recreate the original directory and files during extraction. A ZIP archive can contain both binary and text files because the archive format itself simply stores compressed representations of its contents. Compression reduces storage requirements and makes groups of files easier to distribute. Password protection or encryption may also be applied in supported archive formats.
Databases and application-specific data files frequently use binary structures as well. A database engine may store records, indexes, transaction information, page headers, and internal metadata in a format optimized for fast access rather than human readability. Games may store maps, textures, models, or saved states in binary files designed specifically for the game engine. Office documents can also contain binary or compressed structured data depending on the format and software generation. Scientific applications use binary formats to store large arrays of measurements efficiently. The variety of examples shows that binary files are not one particular file type but a broad way of representing structured digital information.
How Software Reads and Writes Binary Files
A program normally reads a binary file by opening it in a mode that preserves the exact byte sequence. The software then retrieves bytes from selected positions and interprets them according to the expected file specification. A program may begin by reading a fixed-size header before deciding how much additional data to retrieve. It can convert groups of bytes into numbers, strings, timestamps, or more complicated objects. Validation is important because the file may be incomplete, corrupted, or intentionally malformed. Robust software checks sizes and values instead of assuming every binary input is trustworthy.
Programming languages provide file input and output APIs that allow developers to work with binary data directly. Instead of reading a line of text, a program can request a particular number of raw bytes. Those bytes may be stored in arrays, buffers, streams, or specialized binary data types depending on the language. Developers can then unpack values using the correct sizes and byte order. Many languages also provide libraries that already understand popular formats such as images, compressed files, or multimedia containers. Using established libraries is usually safer than manually implementing a complicated format from scratch.
Writing a binary file involves performing the opposite process. Software converts internal program values into the exact sequence of bytes required by the destination format. It may write a header first, followed by data blocks, indexes, checksums, and other structural elements. Numerical values must use the required width and endianness, while text embedded inside the binary format must use the specified character encoding. Some formats require offsets that cannot be calculated until later sections have been generated. Developers may therefore need to reserve space temporarily and return to update earlier parts after the rest of the file is written.
Serialization is a closely related concept in which in-memory objects or data structures are converted into a format suitable for storage or transmission. Binary serialization can encode numbers, strings, lists, and complex structures more compactly than many text-based alternatives. Network protocols and distributed systems may use structured binary serialization to reduce bandwidth and processing overhead. However, serialized formats need well-defined schemas or conventions so receiving software knows how to reconstruct the original information. Version compatibility is also important because applications may add or remove fields over time. Poorly designed serialization can make old stored data difficult to read after software evolves.
Error handling is particularly important when dealing with binary files because corruption may not be visually obvious. A damaged header can cause software to misinterpret the entire structure, while an incorrect length field can make a program read beyond the intended section. File formats may use checksums, hashes, internal consistency rules, or redundant information to detect corruption. Security-conscious programs also impose limits on sizes and nesting to protect against malicious files designed to consume excessive resources. Many historical software vulnerabilities have involved unsafe parsing of complex binary formats. Careful validation is therefore an essential part of binary file processing.
How to Open and Inspect a Binary File
The best way to open a binary file is usually with an application designed for its format. An image file should be opened in an image viewer or editor, while an audio file belongs in a compatible media player. Compressed archives can be opened with archive software, and executable files are handled by the operating system or development tools. If the file extension is known and correct, it often provides the first clue about which application is appropriate. Operating systems can also maintain file associations that launch the expected software automatically. Choosing the correct application allows the raw binary structure to be translated into information meaningful to the user.
If the file type is unknown, examining its metadata or file signature can provide useful clues. Many formats begin with recognizable sequences of bytes that identify the expected structure. File identification utilities can compare the beginning of a file against known signatures and suggest a likely format. This method is more reliable than relying only on the extension because extensions can be missing, incorrect, or intentionally renamed. Metadata may also reveal which program created the file or which version of the format it uses. Once the format is identified, the appropriate viewer or parser can usually be selected.
A hex editor provides a more technical way to inspect binary files directly. Instead of attempting to display every byte as a normal character, a hex editor represents each byte using hexadecimal notation ranging from 00 to FF. Many tools also display printable character interpretations beside the hexadecimal values. Developers can use this view to identify headers, compare files, inspect offsets, or troubleshoot corrupted data. Hexadecimal is convenient because two hexadecimal digits represent exactly one byte. However, understanding the meaning of the values still requires knowledge of the underlying file structure.
Technical users may also use command-line tools, debuggers, disassemblers, and format-specific analyzers to inspect binary information. Executable analysis tools can display sections, imported libraries, machine instructions, and other program metadata. Image utilities may expose color profiles and compression details, while archive tools can list entries without extracting them. Network analysis programs decode binary protocol packets into structured fields. These tools are valuable because they interpret the bytes according to known standards rather than forcing users to calculate everything manually. Specialized inspection is usually faster and less error-prone than reading a large file entirely through hexadecimal values.
Editing a binary file manually should be done cautiously because changing even one byte can have significant consequences. A modification could invalidate a checksum, corrupt compressed data, change an executable instruction, or make offsets point to incorrect locations. Backups should be created before experimenting with important files. Users should also avoid executing unknown binary files simply because they can open or download them. Executables and certain document formats can contain malicious code or exploit vulnerable software. Inspecting a binary file safely is different from trusting it enough to run.
Advantages and Limitations of Binary Files
One advantage of binary files is efficient storage of numerical and structured data. Values can often be represented directly using fixed numbers of bits rather than converted into textual digits and separators. This difference can reduce file size for large datasets containing millions of numbers. Binary formats can also organize information into indexes and blocks that enable fast random access. Software may jump directly to a particular section instead of scanning the complete file sequentially. These characteristics make binary storage useful for databases, multimedia, scientific computing, games, and other performance-sensitive applications.
Performance can be another benefit because programs may perform less conversion when the stored representation closely matches the form needed in memory. Reading four bytes as a fixed-width integer can be simpler than reading several text characters and converting them into a number. Structured binary formats can also avoid repeated field names and punctuation found in verbose textual formats. Compression may further reduce disk and network usage. The actual performance advantage depends on the design of the format and implementation rather than merely on whether the file is labeled binary. Poorly designed binary structures can still be slow or unnecessarily large.
Binary formats can support rich features that are difficult to represent efficiently using plain text alone. Multimedia files can combine compressed audio, video, timestamps, metadata, and subtitles inside one organized container. Executables store machine instructions together with relocation data, resources, and loading information. Databases maintain indexes and page structures optimized for querying and transactional updates. These formats are designed around their specific workload instead of general human readability. Specialized design can deliver better performance and capabilities when software is the primary consumer. This flexibility is one reason binary formats appear throughout modern computing.
The main disadvantage is reduced transparency for humans. A developer cannot normally open an arbitrary binary file in a text editor and understand its complete contents immediately. Specialized tools, documentation, or libraries are needed to decode the structure. This can make manual troubleshooting and data recovery more difficult when software is unavailable. Proprietary binary formats can create additional compatibility problems if only one vendor understands the specification. Text-based formats are often preferred when easy inspection, manual editing, long-term accessibility, and interoperability are more valuable than maximum compactness.
Binary compatibility can also become difficult as formats evolve. Software may expect fields at specific byte offsets or interpret values differently between versions. Adding new functionality without carefully designing versioning rules can prevent older applications from reading newer files. Corruption can also spread through a binary structure if one damaged field causes later offsets or lengths to be interpreted incorrectly. Good formats therefore include version markers, validation, optional fields, and clear compatibility rules. Binary files offer powerful advantages, but those benefits depend heavily on thoughtful format design and reliable parsing software.
Frequently Asked Questions About Binary Files
What is a binary file in simple terms?
A binary file is a computer file whose bytes represent structured data rather than primarily human-readable text characters. Images, audio files, videos, executables, archives, and many databases are common examples.
What is the difference between binary and text files?
A text file stores information mainly as encoded characters that people can read in a text editor. A binary file can use byte values to represent numbers, compressed information, machine instructions, multimedia, or other structured data that normally requires specialized software.
Is every computer file technically binary?
At the physical level, yes, because computers ultimately store files as bits. The term binary file is normally used to distinguish non-text structured formats from files intended to be interpreted primarily as character sequences.
Can I open a binary file in a text editor?
You can often open one, but the result will usually contain unreadable symbols because the editor interprets arbitrary bytes as text characters. A format-specific application or hex editor is generally more appropriate.
What are common examples of binary files?
Common examples include JPEG and PNG images, MP3 audio files, MP4 videos, executable programs, ZIP archives, compiled libraries, database files, and many application-specific data formats.