
What Is a Code Compiler? How Compilation Works
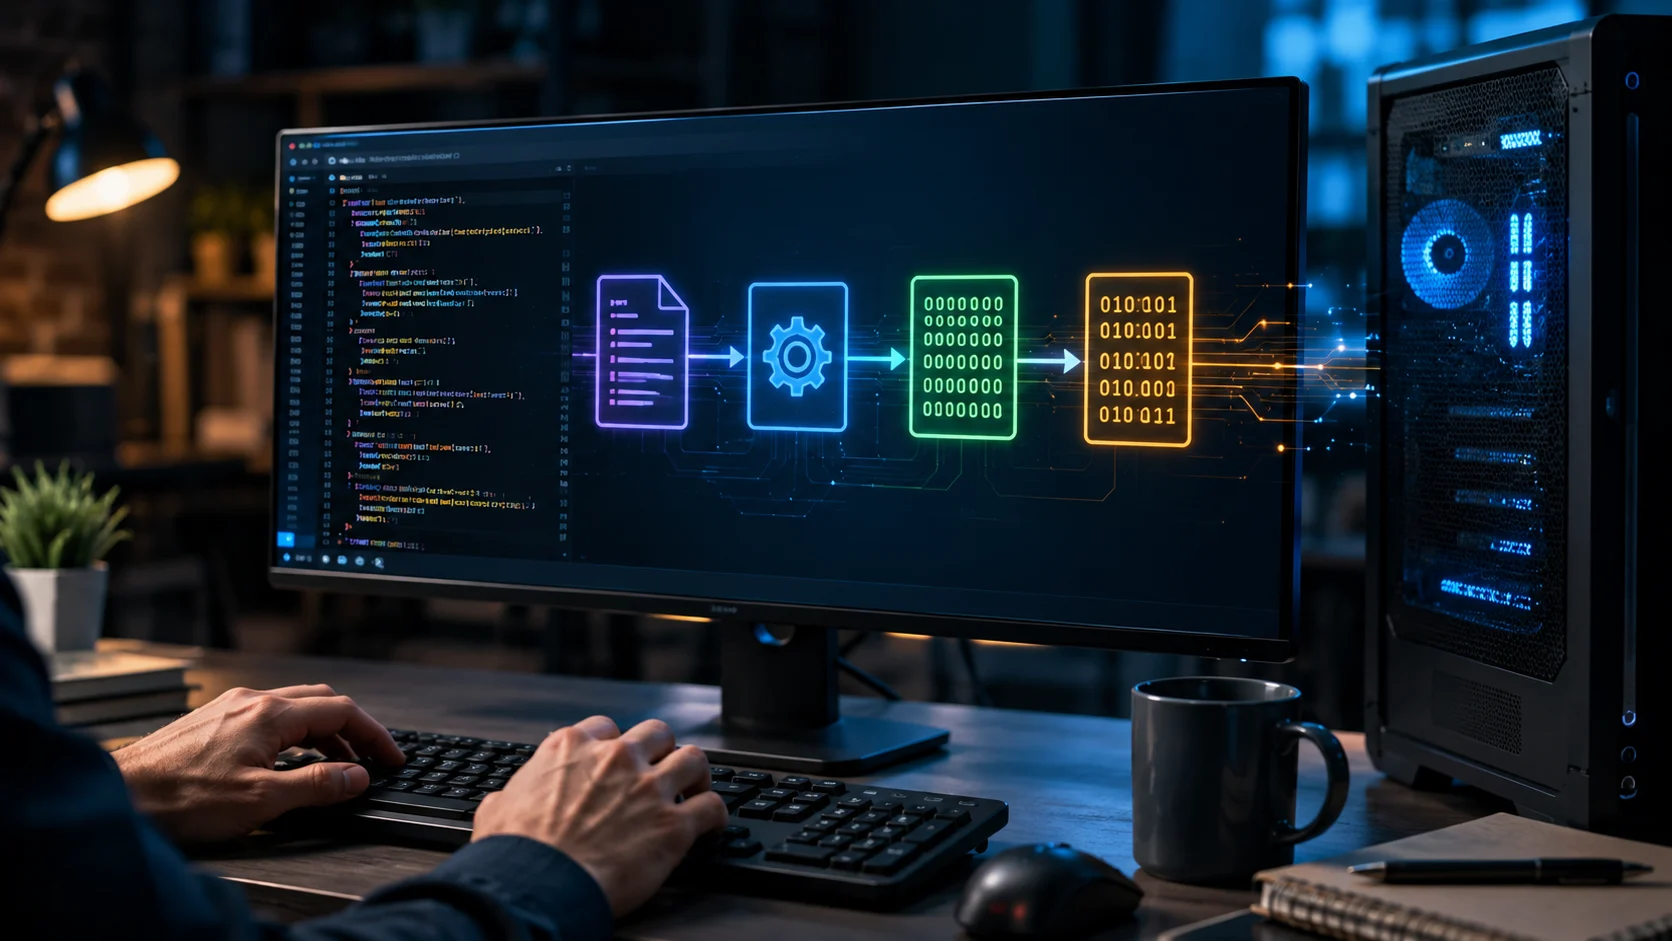
A code compiler is a software tool that translates source code written by programmers into another form that a computer can execute or process more efficiently. In many cases, that means converting a high-level programming language such as C, C++, or Rust into machine code understood directly by a processor. Compilers perform much more than simple translation because they also examine syntax, check data types, detect certain programming errors, optimize instructions, and prepare code for linking into a finished program. Without compilers, developers would often need to write low-level processor instructions manually. Modern compilers therefore provide an essential bridge between human-readable programming languages and computer hardware. They are foundational tools in software development, operating systems, embedded computing, game development, and application engineering.
Compilation may happen before a program is distributed, while an application is starting, or even dynamically while software is already running. Different programming languages and platforms use different approaches, including ahead-of-time compilation, just-in-time compilation, bytecode compilation, and combinations of compilation with interpretation. A modern compiler can also target several processor architectures, optimize code for performance or size, and generate detailed error messages when source code does not follow language rules. Development tools often hide many of these steps behind an integrated development environment or build command. Understanding how compilation works makes programming errors, executable files, build systems, and software performance much easier to understand. This guide explains compiler meaning, compilation stages, compiler examples, optimization, linking, and how compilers differ from interpreters.
What Is a Code Compiler?
A code compiler is a program that reads source code written in one programming language and transforms it into another representation while preserving the intended behavior of the program. The most familiar example is a compiler that converts high-level code into machine instructions for a particular CPU architecture. A programmer may write a statement such as adding two variables, while the compiler determines which registers, memory locations, and processor instructions should perform that operation. This allows developers to work with understandable concepts instead of individual binary instructions. The resulting output may be an executable file, object code, assembly language, bytecode, or another intermediate format. The exact output depends on the language, compiler, and software platform.
Source code is designed primarily for human programmers rather than processors. It may contain variable names, functions, classes, loops, conditions, modules, and other abstractions that make complex software easier to organize. A processor, however, ultimately works with instructions represented in a machine-specific format. The compiler connects these two worlds by analyzing the meaning of the source code and producing instructions or representations that can be executed later. This process must follow the formal rules of the programming language precisely. If the source code violates those rules, the compiler normally stops or reports errors instead of creating a valid program.
Compilers are often associated with languages such as C, C++, Rust, Go, Swift, and Fortran because these languages commonly produce native executable code through compilation. However, compilation is not limited to languages that generate machine code directly. Java source code is commonly compiled into Java bytecode, which is later executed or further compiled by a Java Virtual Machine. C# follows a similar model within the .NET ecosystem, where source code is transformed into an intermediate representation before runtime execution. Modern JavaScript engines also compile frequently executed code internally even though JavaScript is traditionally described as an interpreted language. The boundary between compiled and interpreted languages is therefore more flexible than many beginner definitions suggest.
A compiler also provides an important quality-control step before software runs. It can detect syntax errors such as missing punctuation, improperly formed expressions, or invalid language constructs. It may also detect type mismatches, inaccessible variables, incorrect function arguments, unreachable code, or other problems depending on the language. These checks prevent many errors from reaching users in the first place. However, a successful compilation does not guarantee that a program is logically correct. Software can compile perfectly and still contain bugs if the programmer’s instructions produce the wrong result.
Compilers are themselves sophisticated software systems created using principles from computer science, language theory, optimization, and processor architecture. They need to understand the grammar and semantics of a programming language while also understanding how to produce efficient output for the target environment. Large compiler projects may support several languages, processors, operating systems, and optimization levels. Some are open source and widely used across the software industry, while others are developed specifically for particular hardware or development platforms. Compiler design continues to evolve as processors, programming languages, security requirements, and software workloads change. This makes compilers both practical development tools and highly advanced pieces of software engineering.
How Does Compilation Work?
Compilation begins when the compiler receives one or more source code files as input. These files contain statements written according to the syntax and rules of a particular programming language. The compiler reads the text and breaks it into meaningful components such as keywords, identifiers, operators, numbers, punctuation, and string values. It then determines how those components relate to one another according to the language grammar. If the code contains an invalid structure, compilation may stop with an error message. This early analysis ensures that later stages work with code that can be interpreted according to the programming language specification.
After understanding the basic structure, the compiler analyzes what the program is intended to mean. It checks whether variables have been declared correctly, whether operations use compatible types, and whether functions receive appropriate arguments. The compiler may also determine which names refer to local variables, global symbols, classes, modules, or library functions. These checks are commonly described as semantic analysis because they go beyond grammar and examine meaning. A statement can be syntactically valid but semantically incorrect, such as trying to add incompatible data types. Semantic analysis helps prevent these problems before machine instructions are generated.
Many compilers then transform source code into an intermediate representation, often shortened to IR. Intermediate representation is an internal form that is easier for the compiler to analyze and optimize than the original source language. It can also separate the front end of the compiler, which understands the programming language, from the back end, which understands processor architectures. This design allows one compiler framework to support several source languages and several hardware targets more efficiently. Optimization passes can operate on the IR without needing to understand every detail of the original syntax. The compiler later converts the optimized representation into lower-level instructions.
Code generation converts the processed representation into assembly language or machine code suitable for the target processor. The compiler must choose processor instructions, allocate registers, calculate memory access, and organize control flow efficiently. Different targets may require completely different machine instructions even when the original source code is identical. A program compiled for an x86-64 processor cannot normally run directly on an ARM processor without recompilation or emulation. Cross-compilers are specifically designed to run on one platform while generating code for another target. This capability is particularly important in embedded systems and operating system development.
The final stages often involve assembling and linking. An assembler converts generated assembly instructions into object code containing machine instructions and related metadata. A linker then combines object files with required libraries and resolves references between functions or data located in different files. The result may be a standalone executable, shared library, firmware image, or another deployable binary. Some libraries are linked directly into the final program, while others are loaded dynamically when the application starts. Although developers may experience compilation as a single command, a complete build can therefore involve several distinct tools and transformations.
Main Phases of a Compiler
Lexical analysis is usually one of the earliest formal phases in a compiler. The lexical analyzer, sometimes called a lexer or scanner, reads individual characters and groups them into tokens that carry useful meaning. For example, the text total = price + tax may be divided into identifiers, an assignment operator, and an addition operator. Whitespace and comments may be discarded or handled according to the language rules. Tokenization makes the source code easier for later compiler stages to process. Instead of reasoning about individual letters, the parser can work with meaningful language elements such as keywords, numbers, and operators.
Syntax analysis follows tokenization and determines whether the sequence of tokens forms valid language structures. This stage is usually performed by a parser using the grammar defined for the programming language. The parser may build a structure known as an abstract syntax tree, or AST, representing relationships between expressions and statements. For example, it can determine that multiplication should occur before addition according to operator precedence rules. Missing brackets, unexpected keywords, or incomplete statements are often discovered during this phase. A clear syntax error message helps the programmer locate and correct the invalid structure.
Semantic analysis checks whether syntactically valid code also makes logical sense according to the programming language’s rules. The compiler can verify data types, variable declarations, function signatures, scope rules, and allowed operations. If a function expects an integer but receives an incompatible object, a statically typed compiler may report the issue before execution. The compiler also builds symbol tables containing information about variables, functions, classes, and other named elements. These tables help resolve which declaration each identifier refers to. Semantic analysis therefore connects the structure of the program with the meaning required for correct translation.
Intermediate code generation creates a lower-level representation of the analyzed program. This internal format may use instructions that resemble assembly language while remaining independent of a specific processor. Compilers use intermediate representations because they make optimization and portability easier. A language front end can translate several different programming languages into a shared IR, while multiple back ends can convert that IR into code for different processors. This modular architecture is used by major compiler infrastructures. It allows compiler engineers to improve optimization techniques without rewriting every language-specific component from the beginning.
Optimization and final code generation occur after the compiler has a sufficiently detailed representation of the program. Optimization attempts to improve performance, reduce executable size, lower memory use, or otherwise improve output without changing the intended result. The compiler then maps the optimized representation onto instructions supported by the target CPU or virtual machine. Register allocation determines which temporary values can remain in fast processor registers, while instruction selection chooses appropriate hardware operations. Scheduling may rearrange safe instructions to improve processor efficiency. These stages turn a high-level program into code that can operate effectively on real computing hardware.
Compiler vs Interpreter vs JIT Compiler
A traditional ahead-of-time compiler translates source code before the finished application is executed. Languages such as C and C++ commonly use this model, producing native binaries that the operating system can load later. Because much of the translation work has already happened, the program can begin running without repeatedly analyzing the original source code. Native compilation can also allow extensive optimization for a particular processor architecture. The disadvantage is that developers may need separate builds for different operating systems or CPU families. Changes to the source code also require recompilation before the new version can run.
An interpreter takes a different approach by executing program instructions through another software environment rather than producing a complete native executable beforehand. Traditionally interpreted languages can offer rapid development because programmers can change code and run it immediately without a separate visible compilation step. Python is often presented as an interpreted language, although real implementations may first compile source code into bytecode internally. The interpreter or virtual machine then executes that intermediate form. This shows why the distinction between compilation and interpretation is not always absolute. Many language implementations combine several techniques behind the scenes.
Just-in-time compilation, commonly called JIT compilation, performs compilation during program execution. Instead of compiling every part of an application fully before startup, a runtime system observes which pieces of code are being used and may compile frequently executed sections into optimized machine code. This approach is common in environments such as Java virtual machines and modern JavaScript engines. The runtime can use information about actual program behavior when deciding how aggressively to optimize. Frequently executed paths may receive more optimization than rarely used functions. JIT compilation therefore combines some flexibility of interpretation with much of the speed of native execution.
Ahead-of-time and JIT compilation involve different performance tradeoffs. Ahead-of-time compilation can reduce runtime overhead because optimization occurs before users launch the program. JIT systems may require additional startup time or memory because compilation happens while the application is running. However, JIT compilers can optimize using real runtime information that an ahead-of-time compiler may not know. They can identify the exact types or functions commonly used and create specialized machine code. Some modern platforms combine both approaches to achieve faster startup and strong long-term performance. The right technique depends on language design, deployment environment, and application requirements.
The compiler-versus-interpreter distinction is therefore best understood as a description of implementation strategy rather than a permanent property of every programming language. A language specification defines what programs mean, while separate implementations decide how to execute them. One implementation might interpret code, another might compile it ahead of time, and another might combine bytecode with JIT compilation. Even programming tools can switch strategies depending on development and production needs. Developers should focus on how their particular runtime and build system operate. Understanding these approaches helps explain startup speed, portability, deployment size, debugging behavior, and application performance.
Common Compiler Examples and Compiled Languages
GCC, the GNU Compiler Collection, is one of the most widely recognized compiler toolchains. It supports languages including C, C++, Fortran, and several others, depending on the installed components. GCC can generate code for many processor architectures and is used extensively in Linux development, embedded systems, operating system software, and open-source projects. Developers can select optimization levels, debugging information, warning options, and target-specific settings through command-line flags. GCC usually participates in a larger toolchain containing assemblers and linkers. Its long history and broad platform support make it an important example of a production-grade compiler ecosystem.
Clang is another major compiler commonly used for C, C++, Objective-C, and related development. It is built around LLVM, a modular compiler infrastructure that provides reusable intermediate representations, optimizers, and code generation systems. Clang is known for strong diagnostic messages and integration with modern development tools. LLVM’s architecture also makes it useful beyond traditional C-family compilation because other programming languages can target LLVM’s intermediate representation. Rust, Swift, and many experimental language projects use LLVM components in at least some implementations. This illustrates how modern compiler frameworks separate language analysis from target-specific code generation.
The Rust programming language commonly uses the rustc compiler to transform Rust source code into executable programs or libraries. Rust emphasizes memory safety and ownership rules, so its compiler performs extensive analysis before code is allowed to build successfully. Some beginners find the error messages strict, but those checks are designed to prevent categories of memory and concurrency problems before runtime. Rust compilation commonly uses LLVM for lower-level optimization and machine code generation. The result is native code capable of performance suitable for systems programming. This demonstrates how a compiler can enforce important language guarantees in addition to translating syntax.
Java uses a different compilation model that illustrates how intermediate code can improve portability. The javac compiler typically converts Java source files into bytecode stored in class files rather than immediately creating processor-specific native instructions. A Java Virtual Machine then loads that bytecode on the target system. The JVM can interpret portions of it and use JIT compilation to convert heavily used code into optimized native instructions. This approach supported Java’s long-standing goal of allowing software to run across multiple platforms with a compatible virtual machine. Compilation therefore still occurs even though the initial compiler output is not a traditional native executable.
C# and the broader .NET ecosystem use a related concept involving intermediate language and runtime compilation. Source code is compiled into an intermediate representation along with metadata that the .NET runtime can understand. The runtime can then transform the relevant code into native machine instructions for the actual operating environment. Modern .NET also provides ahead-of-time compilation options for scenarios where faster startup or particular deployment characteristics are valuable. Similar hybrid approaches appear across many language platforms today. These examples show that a compiler does not need to produce final machine code immediately in order to play a central role in program execution.
What Compiler Optimization Does
Compiler optimization attempts to improve generated code while preserving the behavior defined by the source program. A compiler may remove unnecessary calculations, simplify expressions, reduce memory operations, or replace inefficient instruction patterns with faster alternatives. These changes happen automatically, allowing programmers to write readable high-level code without manually optimizing every machine instruction. Most production compilers provide several optimization levels so developers can balance compilation time, debugging convenience, code size, and runtime speed. Lower optimization levels are commonly used during debugging because generated instructions correspond more closely to source code. Higher levels are often selected for release builds where performance matters more.
Dead code elimination is a common optimization that removes instructions whose results can never affect program output. If a compiler can prove that a calculation is never used, generating machine instructions for that calculation would waste processor time and executable space. Constant folding provides another example by calculating fixed expressions during compilation instead of runtime. An expression involving only known constants can be reduced to a single value before the program runs. Common subexpression elimination can identify repeated calculations and reuse previously computed results where doing so is safe. These techniques demonstrate how compilers improve programs through mathematical and logical analysis.
Inlining can improve performance by replacing a function call with the function’s actual instructions when the compiler determines that doing so is beneficial. This eliminates call overhead and can expose additional opportunities for optimization across the combined code. However, excessive inlining can increase executable size, so compilers use heuristics to decide when it is worthwhile. Loop optimization can similarly transform repeated operations through techniques such as unrolling, vectorization, or invariant-code motion. Modern processors are capable of performing several operations in parallel, and vectorization helps compilers take advantage of specialized SIMD instructions. Effective optimization therefore depends closely on processor architecture.
Optimization can sometimes make debugging more difficult because generated machine code no longer corresponds directly to the original source structure. Variables may be removed, functions may be inlined, and instructions may execute in an order that looks different from the written program. This is why developers often compile debugging builds with limited optimization and additional symbol information. Production builds can then use stronger optimization once functional problems have been resolved. Some performance bugs appear only under optimized conditions, particularly when source code relies on behavior that the language does not guarantee. Compiler warnings and sanitizing tools can help identify many such issues.
Compilers also optimize for goals other than raw execution speed. Embedded systems may prioritize smaller binary size because devices contain limited flash memory. Mobile applications may benefit from code that reduces energy consumption or memory pressure. Security-focused compiler options can add protections against certain memory corruption techniques, even when those protections introduce small performance costs. Profile-guided optimization can use information collected from representative program runs to improve frequently used code paths. Modern compiler optimization is therefore a flexible engineering process rather than simply an attempt to make every instruction execute as quickly as possible.
Compiler Errors, Warnings, and the Build Process
Compiler errors occur when the compiler cannot produce valid output because the source code violates required language rules or contains unresolved problems. A syntax error might be caused by a missing closing bracket, malformed expression, or incorrect keyword placement. Type errors can occur when an operation uses incompatible values or a function receives arguments it cannot accept. Undefined symbols may indicate that the program refers to a function or variable the compiler cannot locate. The compiler normally reports the filename, location, and description associated with the problem. Developers then modify the source and run the build again until the blocking errors have been resolved.
Warnings are different from errors because the compiler may still be able to create the program. A warning indicates that the code is legal enough to compile but may contain suspicious behavior, portability problems, or likely mistakes. Examples include unused variables, implicit type conversions, unreachable statements, or potentially unsafe operations. Experienced development teams often enable strict warning settings because warnings can reveal genuine bugs before software reaches production. Some projects even configure the build system to treat selected warnings as errors. This helps maintain a higher standard of source code quality as the project grows.
Compiler messages are only one part of the larger build process. Real software projects may contain thousands of source files, third-party libraries, generated resources, configuration files, tests, and platform-specific components. Build systems determine which files need compilation and in what order. Tools such as Make, CMake, Ninja, Maven, Gradle, Cargo, and language-specific package systems automate these steps in different ecosystems. They can also invoke the linker, run code generators, execute tests, and package final outputs. The compiler is therefore a critical component inside a broader software construction pipeline.
Incremental builds improve developer productivity by recompiling only components affected by recent changes. If a developer modifies one small source file, rebuilding the entire application from the beginning may waste substantial time. Build systems track dependencies so they can determine which object files or modules need to be regenerated. Modern compilers can also cache intermediate results or support parallel compilation across several processor cores. Large software organizations invest heavily in build performance because slow compilation can reduce engineering productivity. Distributed build systems can even divide compilation work among multiple machines.
Continuous integration systems extend the build process beyond an individual developer’s computer. Whenever code changes are submitted, an automated server can compile the project, run tests, perform static analysis, and produce deployment artifacts. This confirms that the software builds successfully in a controlled environment rather than only on one programmer’s workstation. Reproducible builds further aim to produce identical output when the same inputs and tools are used. These practices improve reliability, security, and collaboration. Compilers therefore operate not just as local programming utilities but as central components of modern software delivery pipelines.
Why Compilers Matter in Modern Software Development
Compilers matter because they allow programmers to work at higher levels of abstraction while still producing efficient instructions for real hardware. Writing an entire modern application directly in machine code would be extremely difficult, error-prone, and closely tied to one processor architecture. High-level languages allow developers to express algorithms, data structures, concurrency, and business logic more clearly. The compiler handles much of the translation into low-level operations automatically. This division of responsibility increases programmer productivity dramatically. It also allows language designers to introduce stronger abstractions without requiring processors to understand those abstractions directly.
Compilers also contribute significantly to software portability. A source code project can sometimes be compiled separately for Windows, Linux, macOS, ARM processors, x86 processors, and other environments using appropriate compiler targets. Developers can keep much of the high-level logic unchanged while compiler back ends generate different machine instructions. Portability is never completely automatic because operating systems and hardware expose different features, but compiler infrastructure reduces the amount of platform-specific work required. Cross-compilation is especially valuable when developers are building software for devices that cannot conveniently compile their own code. Embedded controllers, routers, and operating system images commonly rely on this approach.
Security is another important compiler responsibility. Modern compilers can detect unsafe programming patterns, enforce type rules, and insert runtime protections where appropriate. Languages such as Rust use compilation checks to prevent many forms of invalid memory access before software runs. C and C++ compilers can enable stack protection, control-flow defenses, sanitizers, and warnings that help developers identify vulnerabilities. Compiler optimizations can also remove unreachable or unnecessary code that might otherwise increase attack surface. These protections are not a substitute for secure programming, but they provide an important automated layer within the software development lifecycle.
Compilers help hardware innovation become useful to software developers. Processor manufacturers regularly introduce new instruction sets for vector processing, cryptography, artificial intelligence, and other specialized workloads. Developers do not always need to write those instructions manually because compiler back ends can learn how to generate them from high-level code. Auto-vectorization, for example, can transform ordinary loops into instructions that process several values simultaneously. Compilers may also target GPUs, accelerators, WebAssembly environments, or specialized embedded processors. This makes them an important bridge between evolving hardware capabilities and existing programming languages.
The future of compilation is likely to involve even more automation, runtime adaptation, security analysis, and hardware specialization. Compiler frameworks already combine static analysis, profile-guided optimization, machine-specific tuning, and runtime compilation. New programming languages increasingly use compiler checks to enforce concurrency safety, memory correctness, and stronger type guarantees. Artificial intelligence tools may assist programmers in writing source code, but that source still needs precise translation and verification before hardware can execute it reliably. Compilers therefore remain essential even as software development tools become more automated. Their fundamental job continues to be turning human-designed programs into forms that computing systems can understand and execute efficiently.
Frequently Asked Questions About Code Compilers
What is a code compiler in simple terms?
A code compiler is software that translates programming code written by humans into another form that computers can execute or process. It can also check syntax, detect certain errors, and optimize the resulting code.
What is an example of a compiler?
GCC and Clang are common compilers used for C and C++ development. Other examples include rustc for Rust and javac, which compiles Java source code into Java bytecode.
What is the difference between a compiler and an interpreter?
A traditional compiler translates code before execution, while an interpreter executes or processes instructions through a runtime environment. Many modern languages combine compilation and interpretation, so the distinction is not always absolute.
What are the main stages of compilation?
Common stages include lexical analysis, syntax analysis, semantic analysis, intermediate code generation, optimization, and final code generation. Assembly and linking may then create the finished executable or library.
Does compiled code always run faster?
Compiled native code can often run very efficiently because much of the translation and optimization happens before execution. However, performance depends on the language, compiler, runtime, workload, optimization settings, and hardware, so compilation alone does not guarantee faster software.