
Routing Table: How It Works With Simple Examples
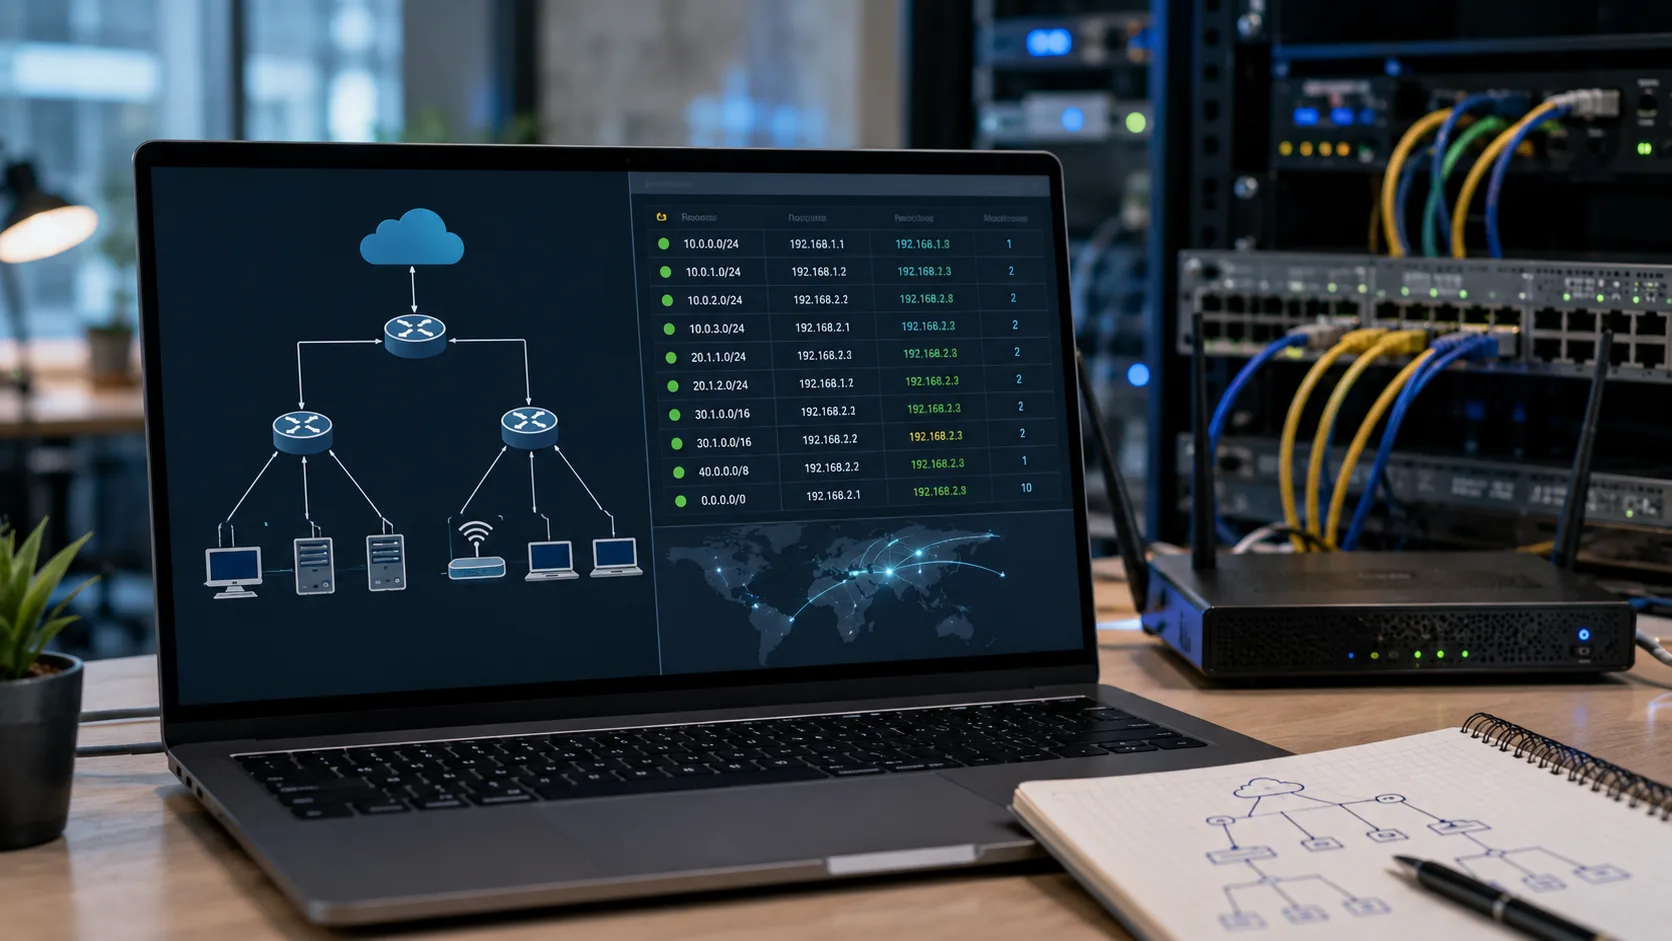
A routing table is a set of rules that a router, computer, or network device uses to decide where IP packets should be sent next. Whenever data travels from one device to another, the system examines the destination IP address and compares it with routes stored in the table. A routing table can contain directly connected networks, manually configured static routes, routes learned through routing protocols, and a default route for destinations that do not match anything more specific. Each entry can also include information such as the next-hop gateway, outgoing interface, network prefix, and route metric. In simple terms, the routing table acts like a map that helps network devices choose a path toward the packet’s destination.
Routing tables are essential to both small home networks and large internet infrastructure. A laptop may use only a few routes, while an enterprise router can maintain thousands of entries and internet backbone routers can work with extremely large routing information sets. The underlying idea remains the same: identify the destination, find the best matching route, and forward the packet through the appropriate interface or gateway. Understanding routing tables makes concepts such as default gateways, subnets, static routes, dynamic routing, and packet forwarding much easier to understand. It also helps when troubleshooting situations where one network can reach another service but a different network cannot. This guide explains how routing tables work using clear examples and practical networking concepts.
What Is a Routing Table?
A routing table is a database maintained by a network device that lists known routes to different IP networks or hosts. Each route tells the device what it should do when a packet is destined for a particular network. The table may specify that the destination is directly connected, that the packet should be sent to another router, or that a default gateway should be used. Routing decisions normally happen automatically every time the device sends or forwards traffic. The user does not need to select the path manually for each packet. Instead, the networking software compares the destination address with the available routing entries and chooses the most appropriate match.
A route normally describes a destination using a network address and prefix length or subnet mask. For example, the network 192.168.1.0/24 represents addresses within a particular IPv4 subnet. A routing-table entry for that network tells the system how packets destined for addresses within that range should be handled. Another route might represent 10.0.0.0/8, which covers a much larger group of addresses. The routing system compares these prefixes with the destination address of each packet. More specific matching routes normally receive preference over less specific routes, a principle known as longest prefix matching.
Routing tables exist on ordinary computers as well as dedicated routers. A laptop connected to Wi-Fi needs to know which destinations are available on its local network and which traffic should be sent toward the default gateway. A server may have several network interfaces and more complex routes that separate internal, management, and internet traffic. Dedicated routers maintain tables specifically to forward packets between many networks. Firewalls, layer-three switches, virtual routers, cloud gateways, and operating systems also use routing tables. IP networking therefore depends on route selection at many points, not only on traditional hardware routers.
Some routing entries are created automatically when a network interface becomes active. If a device receives the address 192.168.1.50/24, the operating system understands that the 192.168.1.0/24 network is directly connected through that interface. Other routes may be entered manually by an administrator. Larger routers can learn routes dynamically through protocols such as OSPF, IS-IS, or BGP. Each source can create entries in the table, while routing logic determines which one should be used when multiple paths exist. The table therefore changes as interfaces, network configurations, and learned routes change.
A routing table should not be confused with a list of every individual packet or active network connection. It contains path information rather than a history of traffic. The table tells the device where traffic should go, while other networking components track connections, address resolution, firewall state, or packet statistics. A route also does not guarantee that the final destination will respond. It only tells the current device how to move the packet toward another network or next hop. Successful communication still depends on the remaining routers, destination system, return route, security controls, and network availability.
How Does a Routing Table Work?
Routing begins when a device has an IP packet that needs to be sent. The networking stack reads the packet’s destination IP address and searches the routing table for entries that could match that address. It then compares the network prefixes in the table and identifies the most specific applicable route. If the destination belongs to a directly connected network, the device can send the packet toward the destination through the appropriate local interface. If the destination is remote, the route may specify another router as the next hop. The packet is then transmitted toward that router, which performs its own routing-table lookup.
Longest prefix matching is one of the most important rules in route selection. Suppose a routing table contains routes for 10.0.0.0/8 and 10.10.0.0/16. A packet destined for 10.10.5.20 matches both routes because that address falls inside both network ranges. However, /16 describes a more specific destination than /8, so the 10.10.0.0/16 route normally wins. This allows administrators to create broad routing rules while adding exceptions for specific subnets. The principle applies throughout IP routing and explains why more specific routes can override general ones without removing the broader entry.
After choosing a route, the device determines the outgoing interface and, when necessary, the next-hop IP address. The next hop is usually another router that is closer to the final destination. A packet may pass through many routers before reaching the target network. Each router normally makes its own independent forwarding decision based on its current routing information. The packet does not usually contain a complete list of every router it should visit. Instead, each step answers one question: where should this packet go next? This hop-by-hop model allows large networks to scale without every endpoint needing detailed knowledge of the entire internet.
If the routing table contains no specific route for the destination, the system may use a default route. In IPv4, a default route is commonly represented as 0.0.0.0/0, which matches every possible IPv4 destination. Because its prefix length is zero, it is less specific than any normal network route. The default route usually points toward a gateway capable of forwarding traffic beyond the local network. Home computers often send most nonlocal traffic toward the home router through this route. If no matching route and no usable default route exist, the device cannot determine where to send the packet and communication fails.
Routing decisions are repeated independently for many packets, even when they belong to the same application connection. Network devices optimize this process heavily because modern routers may forward enormous traffic volumes. Hardware forwarding tables and specialized processors can accelerate route lookups so packets do not require slow general-purpose processing for every decision. The underlying logic still reflects information derived from the routing table. Dynamic changes can alter which path future packets take if a link fails or a better route becomes available. Routing is therefore both a logical selection process and a high-performance packet-forwarding function.
What Information Is Stored in a Routing Table?
The destination network is the most fundamental piece of information in a routing-table entry. It identifies which IP addresses the route applies to. In IPv4, the destination might appear as 192.168.10.0 together with a subnet mask or prefix length such as /24. In IPv6, a route may look like 2001:db8:100::/48. The prefix tells the networking system which part of the address identifies the network. When a packet arrives, the routing software compares its destination IP with these prefixes. Without destination information, the device would have no basis for deciding which route applies.
The next-hop or gateway field tells the device which router should receive the packet next when the destination is not directly connected. For example, a route to 172.16.20.0/24 might specify 192.168.1.1 as its next-hop gateway. The local system sends the packet toward that gateway rather than attempting to reach the remote network directly. The gateway must normally be reachable through one of the device’s local interfaces or through another valid route. In directly connected routes, there may be no separate next-hop router because the destination network itself can be reached through the local link.
The outgoing interface indicates which network connection should be used to transmit traffic. A computer may have Wi-Fi, Ethernet, VPN, loopback, and virtual interfaces active at the same time. A router may have dozens or hundreds of physical and logical interfaces. The route tells the system whether packets should leave through something such as eth0, a wireless adapter, a tunnel, or another interface. Interface selection is especially important on systems with multiple network connections. Without correct routing, traffic may leave through the wrong connection and fail even though the destination network is technically reachable through another interface.
A metric or cost can help choose between multiple routes toward similar destinations. Lower metrics often represent a more preferred route, although the exact interpretation depends on the operating system or routing protocol. One path may be preferred because it has higher bandwidth, fewer hops, lower administrative cost, or a manually assigned priority. Dynamic routing protocols calculate their own metrics according to protocol-specific rules. Static routes may also be configured with different preferences. Metrics become useful when administrators want a primary route and a backup route toward the same destination.
Routing-table entries may include additional information depending on the device and operating system. A route can indicate how it was learned, whether it is active, how long it has existed, or which routing protocol supplied it. Enterprise routers can show administrative distance or preference values used to compare routes learned from different sources. Operating systems may display flags describing gateway usage, route scope, source preferences, or interface state. These details are useful for troubleshooting because two routes that appear similar may have been created in completely different ways. Understanding the fields allows network administrators to determine not only where traffic goes but why that route was selected.
Simple Routing Table Example
Imagine a laptop with the IP address 192.168.1.50/24 connected to a home Wi-Fi network. Its routing table might contain a route for 192.168.1.0/24 through the Wi-Fi interface because that subnet is directly connected. It might also contain a default route 0.0.0.0/0 pointing to the home router at 192.168.1.1. If the laptop sends a packet to 192.168.1.100, it recognizes that the destination belongs to the local subnet and sends it directly through Wi-Fi. If it sends traffic to a public internet address, the default route becomes the applicable path.
Consider the same laptop trying to reach 8.8.8.8. The destination does not belong to the local 192.168.1.0/24 network, so the directly connected route does not match. The default 0.0.0.0/0 route does match because it can represent any IPv4 destination. The laptop therefore forwards the packet toward 192.168.1.1, which is the local gateway. The home router then performs another routing lookup and sends the traffic toward the internet service provider. Several additional routers may repeat the process before the packet reaches the destination network.
Now imagine the laptop establishes a VPN connection to a company network containing 10.50.0.0/16. The VPN software might add a new route stating that 10.50.0.0/16 should be reached through the VPN interface. A packet destined for 10.50.20.25 matches both the VPN route and the default route, but /16 is more specific than /0. The computer therefore sends the packet through the VPN rather than the ordinary internet path. Traffic to unrelated websites can continue using the default gateway. This is an example of split tunneling, where only selected destinations use the VPN.
Suppose another route is added for 10.50.20.0/24 through a different network tunnel. A packet to 10.50.20.25 now matches the /16, /24, and default routes. Longest prefix matching selects /24 because it represents the narrowest and most specific destination range. A packet to 10.50.30.25, however, does not match the /24 route and therefore follows the broader 10.50.0.0/16 VPN route. This simple example shows how network administrators can build general paths and then override them for particular subnets. The routing table handles the selection automatically based on prefix specificity.
If the default gateway becomes unavailable, the laptop may still communicate with devices on its local subnet because the directly connected route remains valid. It could potentially also reach VPN networks if the tunnel remains operational through another path. However, ordinary internet access would fail because the default route no longer leads toward a functioning gateway. This scenario demonstrates why seeing a default route in the routing table does not prove that the gateway itself is reachable. Troubleshooting usually involves checking the route, interface status, gateway reachability, DNS, and return path separately.
Static Routing vs Dynamic Routing
Static routing uses routes that are entered manually by an administrator or configured through automation. A static route remains in place according to its configuration unless someone changes it or the system removes it because of interface conditions. Static routes are simple and predictable, making them useful in small networks or for specific destinations that rarely change. An administrator might create a route to a remote branch network through a known firewall or VPN gateway. Because no routing protocol is required, static routing uses little additional network overhead. The disadvantage is that administrators must maintain the routes as the network changes.
Dynamic routing uses routing protocols that allow routers to exchange information about reachable networks automatically. Instead of manually configuring every possible destination on every router, administrators establish routing relationships and let the routers learn paths from one another. Protocols such as OSPF, IS-IS, and BGP are widely used in different types of networks. If a link fails, dynamic routing can calculate or learn an alternative path when one is available. This adaptability makes dynamic routing essential for large and changing environments. The tradeoff is greater configuration complexity and the need to understand how the routing protocol chooses paths.
OSPF is commonly used inside enterprise and service-provider networks as an interior gateway protocol. Routers exchange information about network topology and calculate paths based on configured costs. If one connection fails, OSPF can update the routing information and direct traffic through another available route. Networks can be divided into areas to improve scalability. The resulting routes appear in the router’s routing information and can be selected for forwarding. OSPF is therefore an example of how routing tables can be populated dynamically rather than exclusively through manual configuration.
BGP, or Border Gateway Protocol, is especially important for routing between large networks on the internet. Organizations and internet service providers advertise which IP prefixes they can reach, and BGP uses policy-based rules to select paths. The global internet depends heavily on this exchange of routing information between autonomous systems. BGP route selection considers several attributes rather than simply choosing the physically shortest path. Policies can influence which provider or connection should be preferred. The routing information learned through BGP is ultimately used to forward packets toward networks far beyond the local organization.
Static and dynamic routing are often used together. A company might rely on OSPF for most internal routes while maintaining static routes for management networks, special appliances, or a default path toward a firewall. Service providers can combine BGP with static routes and other protocols across different parts of their infrastructure. The best approach depends on network size, availability requirements, administrative resources, and how often topology changes. Static routing offers simplicity and control, while dynamic routing offers adaptability and scalability. A routing table can contain entries from both sources simultaneously.
Default Routes, Gateways, and Next Hops
A default route provides a catch-all path for traffic that does not match a more specific routing-table entry. In IPv4, the default route is represented by 0.0.0.0/0, while IPv6 uses ::/0. Because the prefix length is zero, every destination technically matches it, but any more specific route takes priority. Default routes simplify endpoint configuration because a laptop does not need individual entries for every internet network. It only needs to know how to reach local networks and where to send everything else. The gateway receiving that traffic then performs more detailed routing on the device’s behalf.
The default gateway is the router an endpoint normally uses to reach destinations outside its local subnet. A home computer might use 192.168.1.1 as its default gateway, while an enterprise server may use a firewall or layer-three switch. The gateway must be reachable through the local network. If the device cannot reach the gateway at layer two or through an appropriate local path, having the correct IP address configured as a gateway will not make routing work. Address resolution technologies help the device determine how to send local frames toward the gateway. The gateway then removes the local frame and continues routing the IP packet.
A next hop is more general than a default gateway. Any route can specify another router as the next hop toward a particular destination. For example, a router may know that 10.20.0.0/16 should be reached through next hop 172.16.1.2, while all other external traffic follows another gateway. The next hop does not need to be the final destination. It is simply the next routing device expected to move the packet closer. Large networks consist of many such hop-by-hop decisions. Each router needs enough information to choose the next useful step rather than knowing every physical detail of the full journey.
Multiple default routes can exist, particularly on systems with more than one internet connection. A business might have two providers and configure one as primary and another as backup. Metrics or routing preferences determine which default path is normally selected. If the primary connection fails and the routing system detects the failure correctly, traffic can move toward the secondary gateway. More advanced networks may load-balance across several paths. Correct failover depends on more than the routing entry itself because a gateway may remain locally reachable even when its upstream internet service has failed.
Default routes can also appear inside virtual private networks and cloud infrastructure. A full-tunnel VPN may install a route that directs nearly all device traffic through the encrypted tunnel. Cloud subnets often contain route tables where the default destination points toward an internet gateway, NAT gateway, firewall, or virtual appliance depending on design. These environments use the same fundamental routing principles even though administrators configure them through cloud consoles or software-defined interfaces. Understanding the basic relationship among destination, next hop, and default route therefore transfers directly from physical networking into modern virtual networks.
Routing Tables in IPv4 and IPv6
IPv4 routing tables use 32-bit destination addresses and network prefixes such as /8, /16, or /24. A route like 192.168.20.0/24 covers addresses from the associated network according to the first 24 bits of the destination. IPv4 also uses 0.0.0.0/0 as the default route. Traditional subnet masks such as 255.255.255.0 describe the same network size as /24. Modern documentation often prefers prefix notation because it is concise and fits naturally with both IPv4 and IPv6. Route selection then compares destination addresses using these prefixes.
IPv6 follows the same general routing principle but uses 128-bit addresses, allowing an enormously larger address space. A route might appear as 2001:db8:1234::/48 or 2001:db8:1234:1::/64. The default IPv6 route is written as ::/0. Routers still use longest prefix matching to determine the most specific path. Despite the different address notation and size, the conceptual operation is familiar to anyone who understands IPv4 routing. The device compares destination prefixes, chooses a route, identifies the outgoing interface or next hop, and forwards the packet.
IPv6 includes link-local addressing that plays an important role in local communication and routing. Interfaces commonly have addresses beginning with fe80::, which are valid only on the local link. Routers can use link-local addresses as next hops for certain IPv6 routes. Because the same link-local range exists on many interfaces, the interface identifier becomes particularly important when interpreting these routes. IPv6 routing tables can therefore show scope and interface information that may initially look unfamiliar to users accustomed only to IPv4. The underlying purpose remains selecting the correct local path toward the next device.
Dual-stack systems run IPv4 and IPv6 simultaneously and therefore maintain routing information for both protocols. A website may be reachable through both address families, and the operating system can choose which destination to use based on name resolution and connection logic. IPv4 routes do not directly route IPv6 packets, and IPv6 routes do not apply to IPv4 destinations. Administrators therefore need to troubleshoot both tables when dual-stack connectivity behaves differently between protocols. It is possible for IPv4 internet access to work normally while IPv6 fails because its default route or upstream connectivity is missing.
Network engineers should avoid assuming that IPv6 eliminates the need to understand routing simply because many addresses can be configured automatically. Routers still need routes between subnets, firewalls still need appropriate forwarding paths, and endpoints still require a way to reach remote networks. Dynamic routing protocols also support IPv6 routes. The larger address space changes address planning but not the fundamental need to decide where packets go. Learning routing-table concepts with IPv4 therefore provides a strong foundation for understanding IPv6 networking as well.
How to Read a Routing Table
Reading a routing table begins with identifying the destination column or prefix. Look for directly connected networks, specific remote routes, host routes, and the default route. A host route usually uses the most specific possible prefix, such as /32 in IPv4, and applies to only one address. Broader prefixes represent groups of addresses. When troubleshooting traffic toward a particular destination, list every route that could match and choose the longest prefix. This immediately reveals which path the operating system or router is most likely to select.
Next, examine the gateway or next-hop information. A directly connected route may indicate that no gateway is required because the target subnet is attached to the local interface. Remote routes usually identify another router. Verify that the next-hop address itself is reachable. A route can look correct but still fail if the gateway is on a disconnected interface, has the wrong address, or cannot forward traffic further. Understanding this distinction prevents administrators from stopping troubleshooting as soon as they see the expected destination route. The route provides direction, not a guarantee of end-to-end connectivity.
The interface field reveals where the packet will leave the system. This is especially useful on laptops with Ethernet, Wi-Fi, and VPN adapters or servers with several network cards. If traffic intended for a private corporate network is leaving through the public interface, the routing table may contain a missing or less-specific route. Likewise, a VPN can unintentionally capture traffic that should remain local when its installed prefixes are too broad. Comparing the expected path with the selected interface often identifies these errors quickly. Interface status should also be checked because a route through a disabled adapter cannot provide useful connectivity.
Metrics and preferences become important when several routes have identical or comparable destination specificity. The system may choose the route with the lower metric, depending on its routing implementation. Enterprise routers can additionally compare administrative preferences or protocol-specific values before a route reaches the forwarding table. When two internet gateways exist, these values can determine which is preferred. A route that looks correct may not actually be used because another route has a more favorable preference. Reading the complete table rather than only one matching line is therefore important.
The source or protocol field can explain how a route entered the table. Labels may indicate connected routes, static routes, OSPF, BGP, DHCP, VPN software, or another mechanism. If an unexpected route appears after connecting to a VPN, its source helps explain the configuration change. If a dynamically learned route disappears, the issue may be with a routing-protocol neighbor rather than the destination network itself. Understanding route origin turns the table into a diagnostic tool rather than a simple list. Network administrators can trace not only where traffic goes but which configuration or protocol caused that decision.
Common Routing Table Problems and Troubleshooting
A missing route is one of the simplest routing problems. A device may know how to reach its local network but have no route toward a remote private subnet. If a default route exists, the traffic may be sent toward the wrong gateway instead of the intended internal router. Adding or learning the correct specific route can solve the problem. Administrators should first identify the destination and compare it against every existing prefix. If no suitable route exists, the networking system cannot choose the intended path regardless of whether the remote server itself is functioning correctly.
An incorrect default gateway can prevent access to remote networks while leaving local communication unaffected. A computer may still reach printers and servers on its own subnet because those destinations use the directly connected route. Attempts to reach the internet fail because traffic is sent toward a nonexistent or incorrect gateway. This pattern is a useful troubleshooting clue. Checking the device’s IP address, subnet prefix, and default route often reveals the problem quickly. DHCP configuration can also cause widespread gateway errors if many devices receive the same incorrect network settings automatically.
Overlapping routes can cause traffic to follow an unexpected path. A broad VPN route such as 10.0.0.0/8 may capture traffic that was intended for another private network reachable through a different interface. Adding a more specific route can override the broad one through longest prefix matching, but the network design should still be reviewed for conflicting address ranges. Overlapping private addresses are particularly common after company mergers, cloud expansion, or VPN integration. Route selection may be technically correct according to the table while still producing the wrong business outcome because address planning conflicts.
Asymmetric routing occurs when traffic takes one path toward the destination and a different path back. IP networks can support asymmetric routes in many situations, but firewalls and stateful security devices may reject connections if they see only one direction of the traffic. Troubleshooting therefore requires considering the return route as well as the outbound path. A local routing table can be perfectly correct while the remote network has no route back to the source. Packet captures, traceroute tools, and router tables on both sides can help identify these situations. Successful communication is always a two-way routing problem for ordinary request-and-response traffic.
Route changes can also be caused by dynamic protocols, VPN clients, interface metrics, or operating-system updates. A network may work normally until a tunnel connects and installs a new default route. Dynamic routing can withdraw a path when a neighbor fails, while an interface change can modify route preferences automatically. Troubleshooting should therefore consider what changed immediately before connectivity failed. Comparing routing tables before and after an event can reveal unexpected entries quickly. Effective network diagnosis combines the routing table with interface status, DNS results, firewall rules, ARP or neighbor information, and packet-path testing.
Frequently Asked Questions About Routing Tables
What is a routing table in simple terms?
A routing table is a list of network paths that tells a computer or router where to send IP packets. It matches the destination address with a route, next hop, gateway, or outgoing network interface.
What is an example of a routing-table entry?
A simple entry might say that traffic for 10.20.0.0/16 should be sent through gateway 192.168.1.1. Another common entry is the default route 0.0.0.0/0, which handles destinations that do not match a more specific route.
What is the default route in a routing table?
The default route is the fallback path used when no more specific destination route matches. In IPv4 it is commonly written as 0.0.0.0/0, while IPv6 uses ::/0.
What does next hop mean in routing?
The next hop is the next router or gateway that should receive the packet on its journey toward the final destination. The current device does not need to know the entire path as long as it knows where to send the packet next.
What is the difference between static and dynamic routing?
Static routes are configured manually or through fixed automation, while dynamic routes are learned and updated through routing protocols such as OSPF or BGP. Static routing is simpler, while dynamic routing is better suited to larger networks that need automatic path changes.