
Canary Testing: How It Works, Benefits & Examples
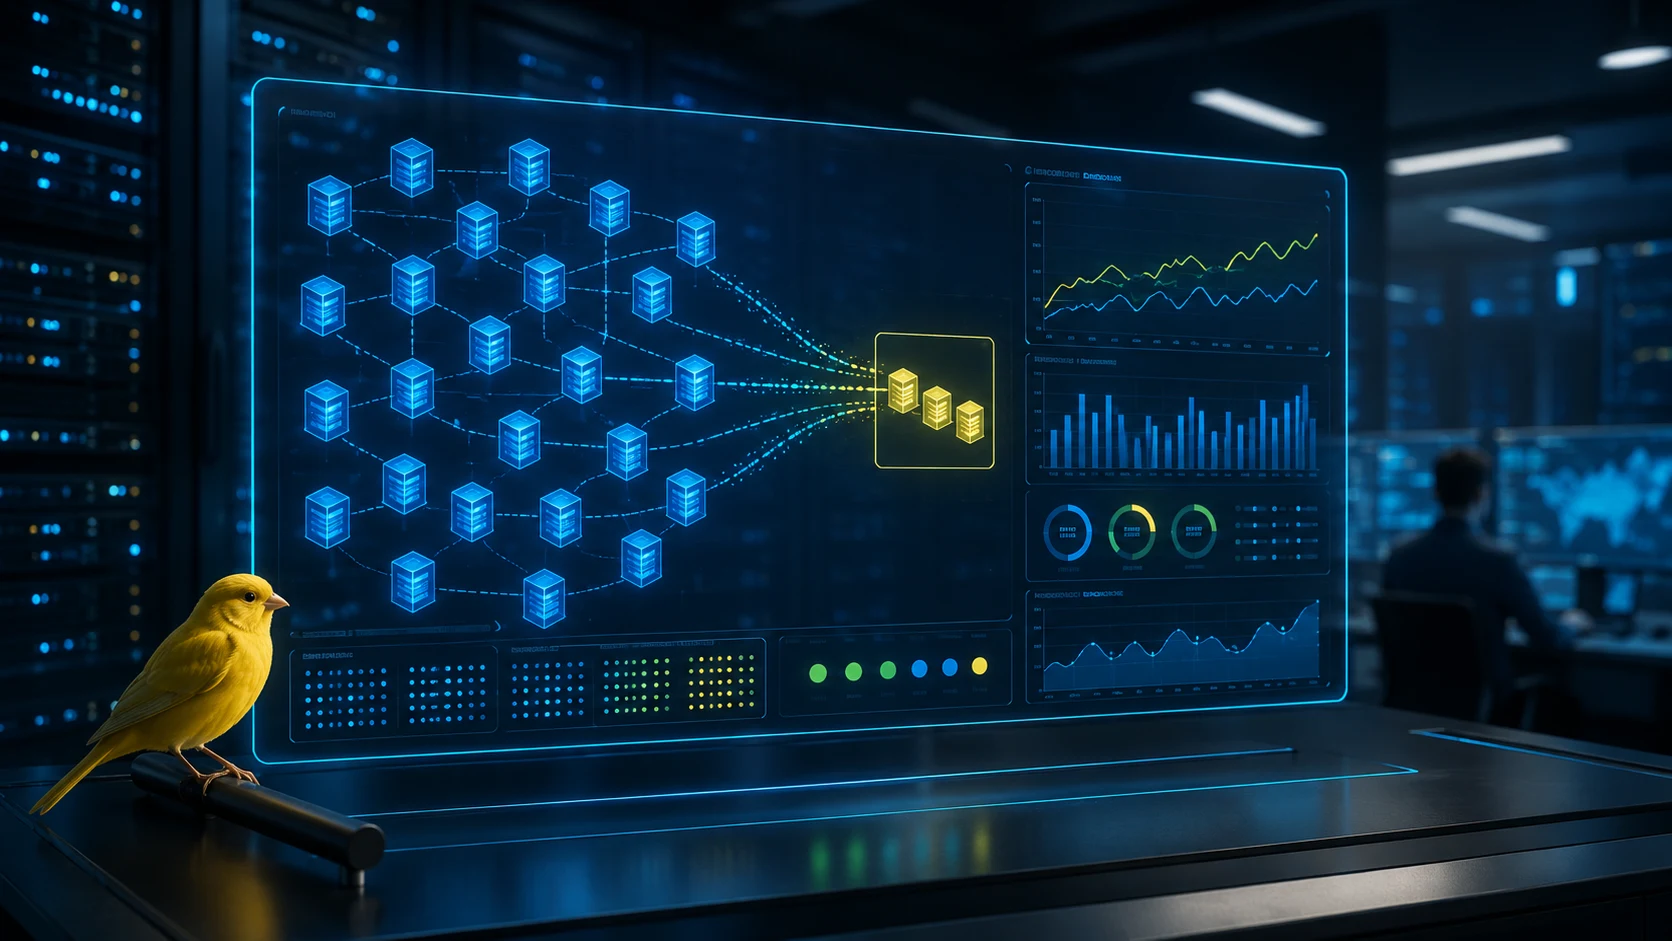
Canary testing is a software release strategy that introduces a new version of an application to a small group of real users before making it available to everyone. Instead of sending an update to the entire production environment at once, teams direct a limited percentage of traffic to the new release and observe how it behaves under real conditions. Engineers monitor metrics such as error rates, latency, resource usage, failed transactions, and user experience to determine whether the release is stable. If the new version performs well, traffic can gradually increase until the deployment reaches the full user base. If serious problems appear, teams can stop the rollout or send traffic back to the previous stable version. This controlled approach reduces the potential impact of software defects.
The term “canary” comes from the historical practice of using canaries as early warning signals in hazardous environments, and the same idea applies to software releases. A small production audience acts as an early indicator of problems that automated tests or staging environments may not reveal. Modern canary testing is closely connected with progressive delivery, continuous integration, continuous deployment, feature flags, observability, cloud infrastructure, and container orchestration. Organizations use it for web applications, APIs, microservices, mobile backends, cloud platforms, and high-traffic digital services where a failed release could affect many customers. The strategy does not replace unit testing, integration testing, or quality assurance. Instead, it adds a final layer of controlled production validation before an update becomes widely available.
What Is Canary Testing?
Canary testing is a method of validating a new software version in production by exposing only a small portion of users or traffic to it initially. The existing stable version continues serving most customers while the canary version handles a carefully selected subset. Engineers compare the behavior of both versions and determine whether the new release is meeting expected reliability and performance standards. If results remain healthy, the canary group can be expanded gradually. This allows teams to gather evidence from real workloads without exposing every user to an unproven change. Canary testing is therefore both a deployment strategy and a risk-management technique for software delivery.
The canary version may contain application code, infrastructure changes, configuration updates, API modifications, or other software changes that require production validation. A team could release a redesigned checkout service to two percent of customers while the remaining ninety-eight percent continue using the previous version. Monitoring then reveals whether payment failures, response times, or customer abandonment increase among the canary users. The new release can progress to ten percent, twenty-five percent, fifty percent, and eventually one hundred percent if results remain acceptable. The percentages are not fixed rules because every organization can design stages around its own risk tolerance. High-risk changes may start with an extremely small audience.
Canary testing differs from testing only in a staging environment because production contains conditions that are difficult to reproduce perfectly elsewhere. Real traffic patterns, geographic differences, third-party dependencies, unexpected user behavior, data scale, network conditions, and infrastructure load can all expose problems that did not appear during preproduction testing. A service might perform correctly with synthetic test traffic but slow down when thousands of real customers make requests simultaneously. Canary releases provide a controlled opportunity to observe these interactions. The goal is not to intentionally expose customers to defective software but to reduce the size of the affected population if an unknown production-specific problem occurs.
Canary testing is commonly associated with continuous delivery and DevOps because frequent software releases increase the importance of safe deployment methods. Teams shipping updates several times per day cannot rely on lengthy manual validation for every production change. Automated canary workflows can deploy a release, split traffic, collect metrics, compare performance, and determine whether progression should continue. If predefined thresholds are exceeded, the deployment system can pause or roll back automatically. This makes canary testing suitable for fast-moving engineering organizations that want frequent releases without accepting unnecessary operational risk. Human review can still remain part of important or unusual deployments.
The strategy is useful for both large and smaller applications, although the implementation can differ. A global service with millions of users can direct one percent of traffic to a canary and still gather substantial data within minutes. A smaller business may need to run the canary for longer because fewer users generate fewer observations. Some organizations use internal employees or selected customer groups as the first canary audience rather than random traffic. Others choose one geographic region, server cluster, or availability zone before expanding elsewhere. The underlying principle remains the same: limit initial exposure, measure real behavior, and increase deployment scope only when evidence supports doing so.
How Does Canary Testing Work?
The process begins after a new software version has passed the organization’s normal development and preproduction testing stages. Developers create a deployable release through the CI/CD pipeline and define how much production traffic should initially reach it. The existing stable release remains active, giving the system a known version to fall back to if necessary. Engineers also establish success criteria before beginning the rollout so the decision is based on measurable results rather than intuition. These criteria may include maximum error rate, response time, CPU usage, conversion performance, or application-specific indicators. Clear thresholds make it easier to determine whether the canary is healthy enough to continue.
Next, the new version is deployed to a limited portion of the production infrastructure. In a containerized environment, this could mean starting a small number of pods running the new application version while most pods continue running the previous release. A load balancer, service mesh, ingress controller, or routing platform can then direct a small percentage of requests toward the canary instances. Other systems may divide users through feature flags or account identifiers instead of raw traffic percentages. The method depends on application architecture and testing goals. Whatever mechanism is used, the new and stable versions operate simultaneously during the observation period.
Monitoring becomes the most important activity once real traffic reaches the canary release. Teams examine technical metrics such as HTTP error rates, request latency, exception counts, memory consumption, CPU utilization, database failures, and dependency errors. They may also monitor business metrics because software can remain technically healthy while producing the wrong business outcome. An ecommerce team could track completed purchases, cart abandonment, payment authorization, or average order value alongside server performance. Logs and distributed traces provide deeper context when unusual behavior appears. Strong observability makes canary testing more reliable because teams need enough information to distinguish normal variation from a genuine release problem.
If the canary performs according to the established criteria, the deployment progresses to another stage. Traffic might increase from one percent to five percent, then twenty percent, fifty percent, and finally one hundred percent. Each stage can have its own observation period depending on how quickly meaningful metrics become available. More users expose the release to a wider variety of devices, workloads, locations, and behavioral patterns. Progressive expansion therefore provides several opportunities to detect problems before the release reaches the full audience. Automated deployment systems can manage these increments without requiring an engineer to modify routing settings manually at every stage.
If significant problems appear, the rollout can stop before exposure grows further. Traffic may be shifted back to the known stable version while engineers investigate the failure. This action is commonly called rollback, although exact recovery behavior depends on the type of change. Application code may be easy to reverse, while database schema changes or irreversible data migrations can require more planning. Strong canary strategies therefore consider rollback compatibility before deployment begins. Once the problem is corrected, teams can create a new release and repeat the process rather than attempting to force an unhealthy canary toward full production.
Key Components of a Canary Deployment
Traffic splitting is one of the central components of canary testing because teams need precise control over who receives the new version. A load balancer can route a percentage of incoming requests toward canary servers while keeping the majority on stable infrastructure. Service meshes can provide more detailed routing rules based on HTTP headers, user identity, geography, or application attributes. Feature flag systems can expose new behavior to selected users without deploying separate application versions in every case. The choice depends on architecture and whether the team wants to test infrastructure, code, features, or several elements together. Accurate routing prevents the canary population from becoming larger than intended.
Observability provides the evidence required to evaluate whether a canary should continue. Metrics show measurable behavior such as request rates, failure percentages, latency percentiles, queue depth, resource usage, and service availability. Logs provide detailed records of application events, while distributed tracing follows individual requests across multiple microservices. Alerting tools can highlight sudden changes that might otherwise be overlooked. Good dashboards should separate canary and stable-version data so teams can compare them directly. If all production metrics are mixed together, a problem affecting two percent of traffic may disappear within the healthy results generated by the remaining ninety-eight percent.
Automated analysis can make canary testing more scalable by comparing metrics according to predefined rules. A deployment platform might determine that the canary error rate cannot exceed the stable version by more than a specified amount. It could also compare latency, resource consumption, and application-specific service-level indicators. If the results remain within acceptable boundaries, the system promotes the release automatically. If thresholds are violated, progression stops and a rollback can be triggered. Automation reduces the need for engineers to monitor dashboards continuously, but thresholds must be designed carefully. Poor criteria can either block healthy releases unnecessarily or allow harmful releases to progress.
Feature flags can complement canary deployments by separating code deployment from feature exposure. Teams can deploy a new capability to production while keeping it disabled for almost everyone. A small group can then receive the feature through a configuration flag without requiring another application deployment. If problems occur, the feature can be disabled quickly while the underlying software remains deployed. This is particularly useful when product teams want to validate functionality gradually rather than test an entire service version. However, excessive feature flags can create configuration complexity, so old flags should eventually be removed after a rollout becomes permanent.
Rollback capability is another essential component because a canary strategy has limited value if teams cannot safely return to a stable state. The previous version should remain available long enough to support fast recovery during the rollout. Deployment systems can retain earlier container images, packages, or infrastructure definitions so they can restore them quickly. Database compatibility deserves special attention because new application code may change stored data in ways older code cannot understand. Teams often use backward-compatible schema migrations when progressive releases are required. Designing for reversibility turns canary testing from passive monitoring into an effective mechanism for limiting the consequences of failed releases.
Canary Testing vs Other Deployment Strategies
Canary deployment and rolling deployment are related but not identical strategies. A rolling deployment gradually replaces old application instances with new ones until every instance runs the updated version. The main objective is often maintaining availability without stopping the entire service during deployment. A canary deployment adds an explicit validation period in which only a controlled population uses the new version while teams evaluate results before expanding. A rolling update can technically become canary-like if progression is paused and analyzed between stages. However, automatically replacing all instances without performance evaluation is better described as rolling deployment rather than deliberate canary testing.
Blue-green deployment uses two complete production environments, typically called blue and green. One environment serves live traffic while the other contains the new release and is prepared separately. After testing, traffic is switched from the old environment to the new one, often in a relatively short transition. Rollback can be fast because traffic can return to the previous environment if it remains intact. Canary testing differs because it normally directs only part of production traffic to the new version at first. Blue-green deployment emphasizes environment switching, while canary deployment emphasizes progressive exposure and real-world validation across multiple stages.
A/B testing also sends different users to different versions, but its primary goal is usually product experimentation rather than deployment safety. A product team might show two page designs to separate audience groups and measure which produces more purchases. Both variants can be technically healthy and intentionally remain active long enough to compare customer behavior statistically. Canary testing, by contrast, normally asks whether a new release is safe and reliable enough to replace the previous one. Business metrics can still influence canary decisions, but the release is usually expected to reach everyone after validation. The two approaches can overlap, yet their primary purposes remain different.
Feature flags provide another form of progressive exposure but operate at the feature level rather than necessarily at the deployment level. The same application version may run across every server while only selected users receive a new capability. This makes flags useful when teams want to control product behavior independently from infrastructure releases. Canary deployment may involve completely separate application binaries or containers that receive different traffic. Organizations frequently combine both techniques because each addresses a different layer of release control. A canary can validate a new service version while flags gradually expose specific functionality contained inside that version.
Traditional all-at-once deployment represents the opposite end of the risk spectrum because the new release becomes available to every user simultaneously. This approach may be appropriate for small applications, low-risk changes, or environments where maintaining multiple versions is impractical. However, a hidden defect can immediately affect the entire customer base. Canary testing reduces this blast radius by making initial exposure intentionally small. The additional safety comes with increased infrastructure, monitoring, and operational complexity. Teams therefore need to decide whether the value of progressive validation justifies that complexity for the systems they operate.
Benefits of Canary Testing
The biggest benefit of canary testing is reduced deployment risk. A defect that appears only in production may affect one percent of users rather than the entire customer base when the rollout begins cautiously. This smaller blast radius gives engineering teams time to detect and correct issues before they become widespread incidents. High-traffic services particularly benefit because even a short full-scale outage can affect large numbers of customers. Canary releases do not eliminate defects, but they change the consequences of discovering them. Instead of assuming every release is safe, the deployment process gathers real evidence before expanding exposure.
Canary testing also provides realistic production feedback that staging environments cannot always reproduce. Real users generate unpredictable input, traffic patterns, network conditions, device differences, and interactions with external services. Production datasets and infrastructure scale can also expose memory, performance, and concurrency problems that remained invisible during testing. A controlled canary gives engineers access to these conditions while limiting overall exposure. This improves confidence that the release works under the environment where it will ultimately operate. The strategy therefore complements automated testing rather than competing with it, providing another validation layer where assumptions meet real usage.
Faster recovery is another major advantage when canary testing is combined with automated rollback. Teams can detect unusual error rates and stop progression before engineers even receive significant customer complaints. Traffic can then return to the stable release while investigation continues. This approach reduces mean time to recovery because the previous version is already running alongside the canary. Engineers do not need to begin building a replacement from scratch during the incident. Recovery becomes a planned part of the deployment process rather than an improvised reaction after a widespread outage has already occurred.
Canary releases can also improve engineering confidence and increase deployment frequency. Teams may be more willing to ship smaller changes frequently when they know each release will receive controlled exposure and monitoring. Smaller releases are easier to understand because fewer code changes are involved, making failures easier to diagnose. Frequent deployments can also reduce the pressure associated with large release days where months of changes are introduced simultaneously. Over time, safe progressive delivery can support a healthier software development culture. The objective is not to move recklessly but to make routine change less risky through automation, measurement, and reversibility.
Business performance can also benefit because canary testing can reveal functional problems that infrastructure metrics alone miss. A new checkout service might return successful HTTP responses while accidentally calculating shipping costs incorrectly. Monitoring completed orders, payment success, or customer support contacts could reveal the issue before the change reaches everyone. Product and engineering metrics therefore work best together during important releases. This is especially valuable for applications where software behavior directly affects revenue, customer trust, or regulated processes. Canary testing helps organizations verify not only that the system remains online but that it continues producing the intended outcomes.
Risks and Challenges of Canary Testing
Canary testing requires strong monitoring because a deployment cannot be evaluated reliably without clear information about how the new version behaves. Teams that lack detailed metrics may mistakenly promote an unhealthy release because the problem is difficult to see. Monitoring must also distinguish canary traffic from stable traffic rather than combining everything into one overall average. A small increase in failures can disappear statistically when most users remain on the stable version. Creating useful dashboards, traces, alerts, and service-level indicators therefore requires deliberate engineering work. Organizations should improve observability before depending heavily on automated canary decisions.
Low traffic can make evaluation difficult because the canary may not receive enough requests to produce meaningful results quickly. An application serving millions of users can gather significant data from a one-percent canary within a short period. A business application with only a few hundred daily users may need hours or days to observe rare failures. Some problems occur only during specific workflows that the canary audience may not perform at all. Teams can address this by selecting representative users, increasing exposure carefully, or combining production observations with synthetic tests. Canary testing is most effective when the observation period matches the volume and behavior of the application.
Maintaining multiple application versions simultaneously can also create compatibility problems. Users may interact with both versions during one session unless routing is configured to keep them consistently assigned. APIs may behave differently between versions, and background workers might process shared data using incompatible assumptions. Database changes are especially challenging because both the old and new application may access the same schema during the canary period. Teams commonly design database migrations in backward-compatible stages so either version can continue operating safely. Without compatibility planning, the canary itself can introduce failures unrelated to the quality of the new code.
Automated promotion creates its own risk when success thresholds are poorly designed. If the system evaluates only server error rates, it may promote software that technically runs but damages customer conversion or produces incorrect results. Thresholds that are too strict can cause frequent false rollbacks, slowing development and reducing confidence in automation. Thresholds that are too loose allow genuine regressions to spread. Teams need baselines that account for normal metric variation and meaningful service objectives. Canary analysis should evolve as engineers learn which signals most accurately predict release health for their specific application.
Operational complexity is another challenge because canary delivery requires traffic management, monitoring, deployment automation, rollback procedures, and compatible infrastructure. Small teams may find that managing these systems costs more than the risk reduction they receive for a low-impact application. Highly regulated environments may also require additional approval and documentation before real customers can receive a partially released version. The strategy should therefore match business risk and technical maturity. Canary testing is not automatically superior to every simpler deployment method. Its value is highest when failed releases have significant consequences and the organization can support progressive delivery reliably.
Real-World Canary Testing Examples
Consider an ecommerce company preparing a new checkout service. The engineering team first deploys the service to production but routes only one percent of checkout sessions to it. They monitor payment authorization, page response time, server errors, completed purchases, and cart abandonment while the stable version handles the remaining users. After thirty minutes of healthy results, traffic increases to five percent and later twenty percent. A rise in payment failures at twenty percent would stop the rollout and return customers to the previous checkout service. This example demonstrates how technical and business metrics can work together during a canary release.
A streaming platform can use canary testing when updating the service responsible for recommending videos or music. A small percentage of users receive results generated by the new service while most continue using the previous algorithm and infrastructure. Engineers monitor response latency, recommendation errors, cache performance, resource usage, and user interaction signals. If the new service consumes significantly more memory or creates slower page loads, the deployment can be paused before it reaches the broader audience. The company may separately conduct product experimentation on recommendation quality after technical stability is established. Canary testing first protects reliability, while later experimentation evaluates whether the feature improves engagement.
A financial application can use a more cautious canary strategy because incorrect behavior may have serious consequences. Internal employees might receive the new transaction-processing version first, followed by a very small group of low-risk customer accounts. Teams monitor transaction failures, reconciliation differences, latency, and unusual support requests before expanding the rollout. Database changes are designed so the previous application remains compatible throughout the test. If any discrepancy appears between expected and recorded transaction values, traffic returns immediately to the stable release. This example shows why canary audiences and progression rules should reflect the risk level of the business process.
A Kubernetes-based software company can implement canary deployment by running separate sets of pods for old and new versions. An ingress controller or service mesh routes five percent of requests to the canary pods while the rest continue reaching stable pods. Monitoring software compares latency, HTTP errors, CPU consumption, and service-specific metrics between the two groups. An automated progressive delivery controller can raise traffic percentages when metrics remain within approved thresholds. If failure rates exceed the limit, the controller stops the rollout and directs traffic back toward stable pods. Kubernetes does not automatically guarantee safe canaries, but its orchestration model makes parallel application versions practical.
A mobile application team can also use canary principles even though app-store distribution differs from web deployment. The company may release the new version gradually to a small percentage of eligible users through staged rollout functionality. Crash rates, startup time, API failures, battery behavior, and customer feedback are monitored before distribution expands. Backend feature flags can provide additional control by keeping risky functionality disabled even after users install the new app. If severe issues appear, the team can pause further rollout while preparing a corrected version. Mobile canaries may be slower to reverse because installed software cannot always be removed remotely, making cautious exposure especially valuable.
Best Practices for Successful Canary Testing
Start with clear success and failure criteria before deploying the canary. Teams should know which technical and business metrics will determine whether the release progresses, pauses, or rolls back. Useful signals might include error rate, latency, saturation, crash frequency, completed transactions, or application-specific service-level indicators. Thresholds should reflect normal production behavior rather than arbitrary numbers chosen immediately before deployment. Engineers should also define how long each observation stage needs to run. A release should not automatically progress merely because no alert fired during the first few minutes.
Keep the initial canary population small enough to limit damage but large enough to generate useful information. The appropriate percentage depends on traffic volume, user diversity, release risk, and how quickly important workflows occur. A service with extremely high traffic might begin below one percent, while a small internal application may need a larger group to gather meaningful results. Early audiences can also be selected intentionally rather than randomly. Employees, beta customers, one region, or accounts with lower business risk can provide useful initial exposure. The rollout should then expand gradually so each stage tests the release under broader conditions.
Invest in observability before relying on canary deployment as a safety mechanism. Application metrics should include version or deployment labels so engineers can distinguish new and old releases easily. Centralized logs should make exceptions searchable, while distributed traces can reveal failures across microservice dependencies. Business dashboards should identify whether customer outcomes change unexpectedly during the rollout. Alerts need to reach the responsible team quickly when thresholds are exceeded. A canary release without strong visibility can create false confidence because problems may be occurring without anyone having the information required to recognize them.
Design releases to be reversible whenever practical. Keep the stable application version available until the canary has completed successfully and consider how database migrations will behave if old code needs to return. Use backward-compatible changes when several application versions must operate at the same time. Feature flags can provide additional control for functionality that may need to be disabled independently from the overall release. Deployment artifacts should be versioned so previous builds can be restored reliably. Teams should test rollback procedures periodically rather than assuming they will work during a high-pressure production incident.
Finally, improve the canary process using results from real deployments. Every rollback should provide information about which signal detected the problem and whether earlier detection was possible. Successful releases can reveal whether observation stages are unnecessarily long or whether certain metrics add little value. Teams should remove outdated checks and add new indicators when recurring failure patterns appear. Deployment automation should evolve alongside application architecture rather than remaining fixed for years. Canary testing works best as a learning system in which each release improves the organization’s ability to identify risk, make evidence-based decisions, and deliver software safely.
Frequently Asked Questions About Canary Testing
What is canary testing in simple terms?
Canary testing releases new software to a small group of users before making it available to everyone. Teams monitor the new version and expand the rollout only when it performs safely.
What is the main benefit of canary testing?
The main benefit is reduced deployment risk because a hidden problem initially affects only a limited portion of users. Teams can stop or reverse the release before the issue spreads across the entire production environment.
What is the difference between canary testing and A/B testing?
Canary testing primarily checks whether a new release is safe and reliable enough for broader deployment. A/B testing usually compares two experiences to determine which performs better according to product or business outcomes.
Can canary testing be automated?
Yes. Modern CI/CD and progressive delivery systems can deploy the canary, split traffic, monitor defined metrics, increase exposure, and trigger rollback automatically when failure thresholds are exceeded.
Is canary testing only used with Kubernetes?
No. Kubernetes is commonly used for canary deployments, but the strategy can work with virtual machines, serverless applications, load balancers, service meshes, feature flags, mobile staged releases, and many other deployment environments.